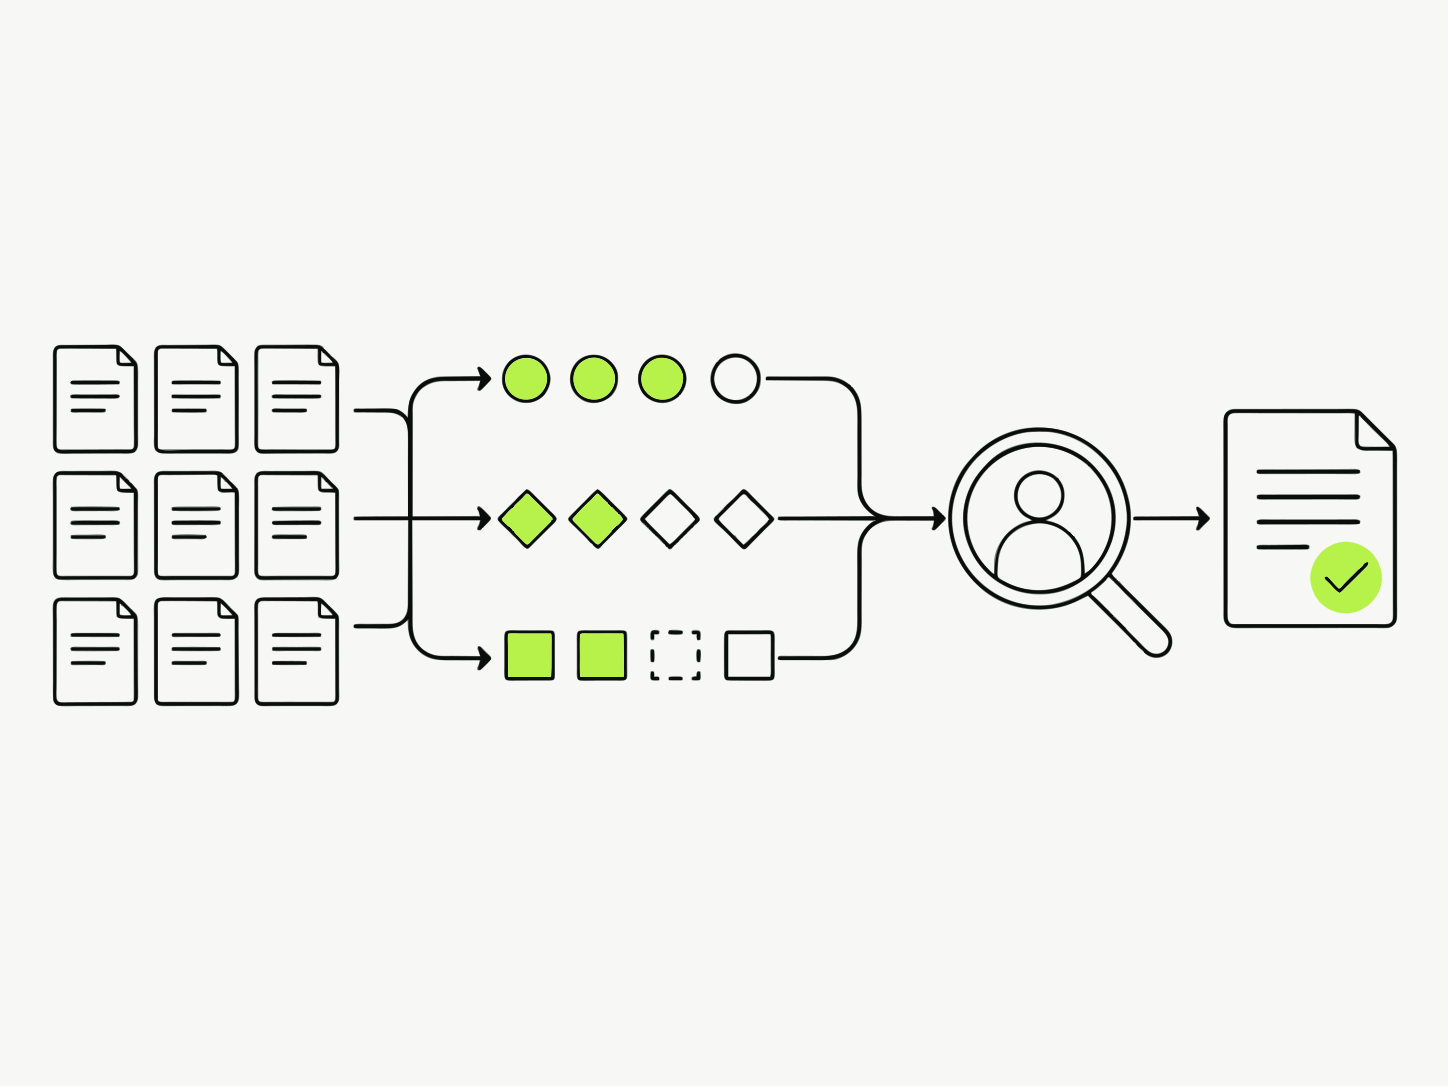
A fixed and declared sample
The pilot benchmark uses 20 shared, non-branded enterprise buyer questions. Accuracy research uses 10 branded questions and up to five official pages. We freeze the market, language, brand comparison set and question bank before collection. Supported engine scope is declared; unavailable engines are not silently replaced with direct model responses.
Three separate outcomes
Mention rate counts unambiguous brand mentions. Recommendation rate counts explicit affirmative shortlist language. Owned citation rate counts citations to approved brand domains. Each brand counts at most once per answer. Sample mention share is the share of brand-answer incidences within the selected comparison set, rather than total market share.
Coverage and missing answers
Failed calls remain unknowns. A valid Google result without an AI Overview counts towards Overview presence but is excluded from answer rates. Comparative rankings require at least 80% valid-question coverage per engine. The report preserves collection dates, provider provenance and the exact question bank. One snapshot does not establish causation or a stable population estimate.
Review and publication
Official pages show the brand’s published position. An analyst reviews claim passages and exact reference passages before confirming discrepancies or approving the final Accuracy report. Industry research evaluates all reviewed brands against shared answers, runs quarterly, and requires editorial approval before public publication. Downloads reuse approved artifacts and never trigger new research.
Business-email eligibility
We reject known personal mailbox, disposable and anonymous relay domains on the server and require mailbox verification. A custom domain does not prove enterprise status or employment by the researched brand. Corporate mail hosted by a shared provider remains eligible. Manual review and report allowances support the policy.